

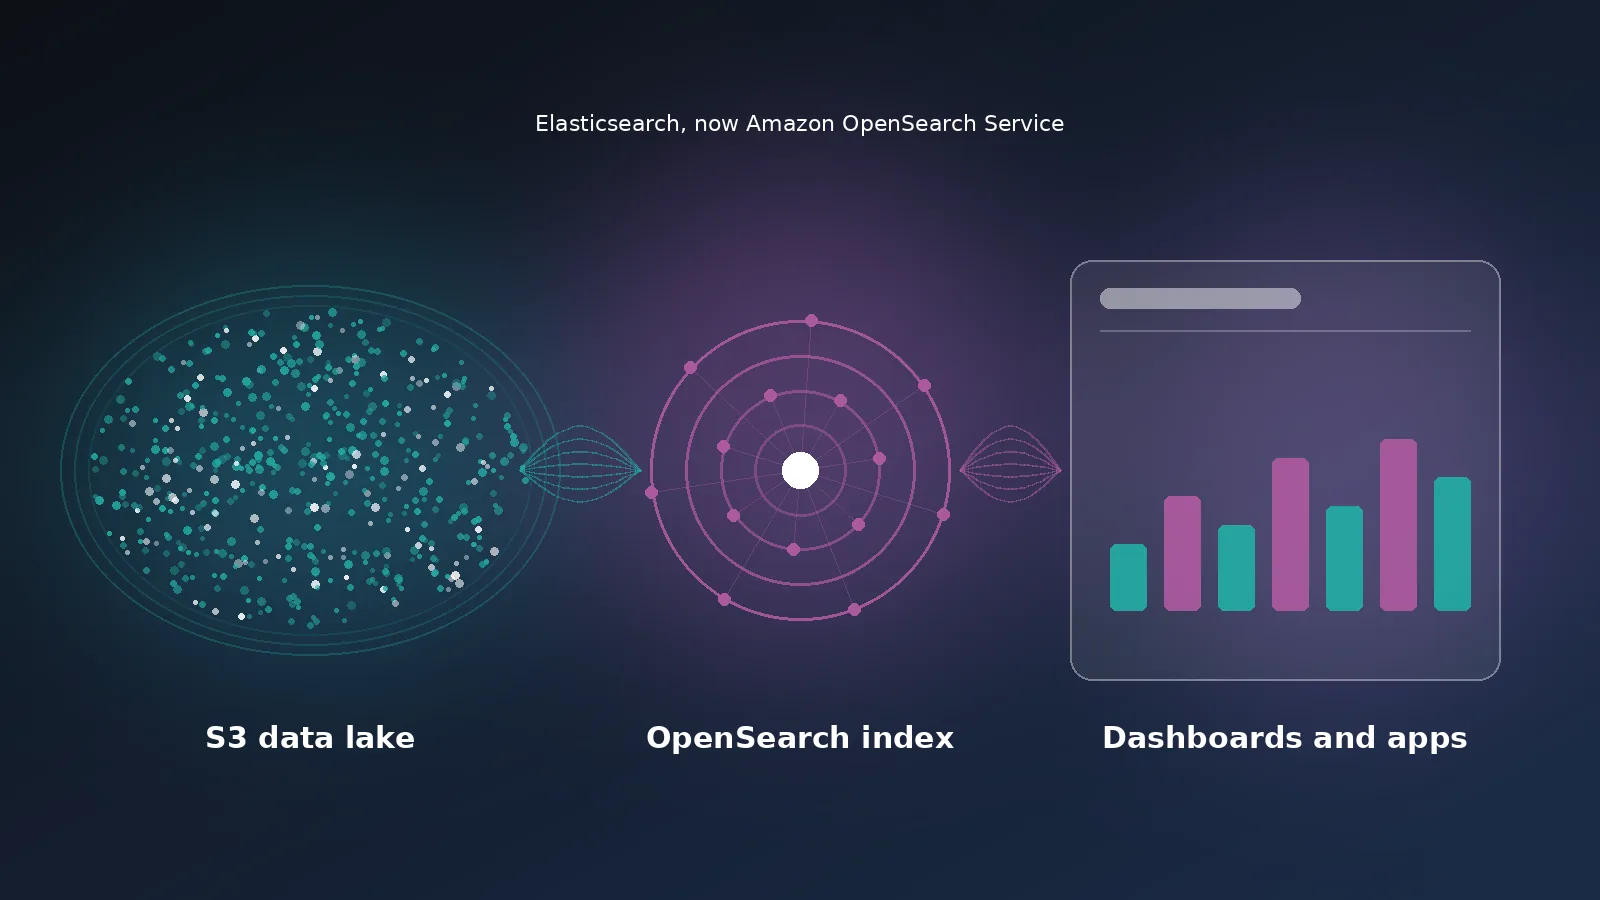
People searching for “AWS Elasticsearch for data lakes” are usually asking one of two questions. Is Elasticsearch still a thing on AWS, and should it be part of my data lake? This post answers both. The short version: the product is now called Amazon OpenSearch Service, it is a very good search and log analytics engine, and it belongs next to a data lake rather than underneath it.
Amazon Elasticsearch Service was renamed Amazon OpenSearch Service in September 2021, after Elastic changed the licence of Elasticsearch and Kibana and AWS forked both projects. OpenSearch is the search engine and OpenSearch Dashboards is the visualisation layer that used to be Kibana. The managed service still offers legacy Elasticsearch versions for existing domains, but new work should start on OpenSearch.
In practice the two are still close relatives. The query language, the index and shard model, the REST API and most client libraries carry over. If you have Elasticsearch experience, it applies. If you are searching the AWS console for Elasticsearch and cannot find it, look for OpenSearch Service.
A data lake on AWS is, at its simplest, files in S3 with a catalogue in Glue and query engines such as Athena, Redshift Spectrum or Spark on top. That stack is excellent at scanning large volumes in bulk: a query that aggregates a year of events across billions of rows is exactly what it was built for. It is poor at the opposite kind of question, the one that wants a handful of specific records back in well under a second.
OpenSearch covers that gap. It keeps an inverted index of the fields you choose, so it can answer four kinds of question that the lake alone answers slowly or not at all:
Athena can do a lookup, but it does so by scanning partitions, so a point query costs about the same as a small aggregation and takes seconds. If an application needs that answer on every page load, the lake is the wrong tool and OpenSearch is the right one.
The expensive mistakes come from treating OpenSearch as a database or as the lake itself.
Not the system of record. An OpenSearch index is a derived view. It can be rebuilt from the source, and it should be, because index mappings change, versions are upgraded and clusters are occasionally lost. S3 is the durable copy. If a dataset exists only inside OpenSearch, that is a backup problem waiting to happen.
Not a replacement for Athena or Redshift. Batch analytics over the whole history, joins across datasets, and anything that reads most of the data belong in the lake engines. OpenSearch aggregations are fast on filtered subsets and painful across everything.
Not a dumping ground for raw data. Every indexed field costs memory and disk on running instances, all day, every day. Indexing all raw data “in case it is useful” is how an OpenSearch bill overtakes the rest of the platform. Index what has to be searched, at the granularity it has to be searched, for as long as it has to be searchable.
The arrangement we build for clients looks the same whatever the industry.
The decision about what to index is the whole design. A domain that holds thirty days of events and the current state of a few million entities stays small and quick. The same domain asked to hold three years of everything becomes the most expensive and most fragile component on the platform.
The lake charges by storage and by data scanned, so an idle lake costs almost nothing. OpenSearch charges by instance hour, and instances never sleep. That difference drives every cost trap:
Index what you have classified, not what you have collected. Our data classification and PII governance work exists because search engines are where personal data becomes easy to find, by design. Before a field is indexed, someone has to have decided whether it should be searchable at all, whether it needs masking or tokenisation first, and who may query it.
On the platform side, the standard controls are well established: domains deployed inside a VPC with no public endpoint, encryption at rest and in transit switched on, fine-grained access control mapping users and roles to indices and to document- or field-level permissions, and audit logging to CloudWatch. These are configuration choices rather than engineering work, but they have to be made before the first index is created, because retrofitting fine-grained access control onto a domain in use is disruptive.
Add OpenSearch to an AWS data lake when most of the following are true:
Keep to the lake engines when the questions are analytical, the history is the point, the latency of a few seconds is acceptable, or nobody can say what should be indexed. A data lake that works is covered in our definitive guide to data lakes on AWS; OpenSearch is the component you add when the guide’s architecture answers every question except the quick ones.
If you are deciding whether a search layer belongs on your platform, or an existing OpenSearch domain has become the cost line nobody can explain, our AWS data lake services cover both the assessment and the build.