

Teams often build one suite of data quality checks and expect it to catch everything. It does not, because “is this valid?” and “is this unusual?” are different questions, and they are answered at different points in the pipeline. Separating them keeps each check simple and each alert meaningful.
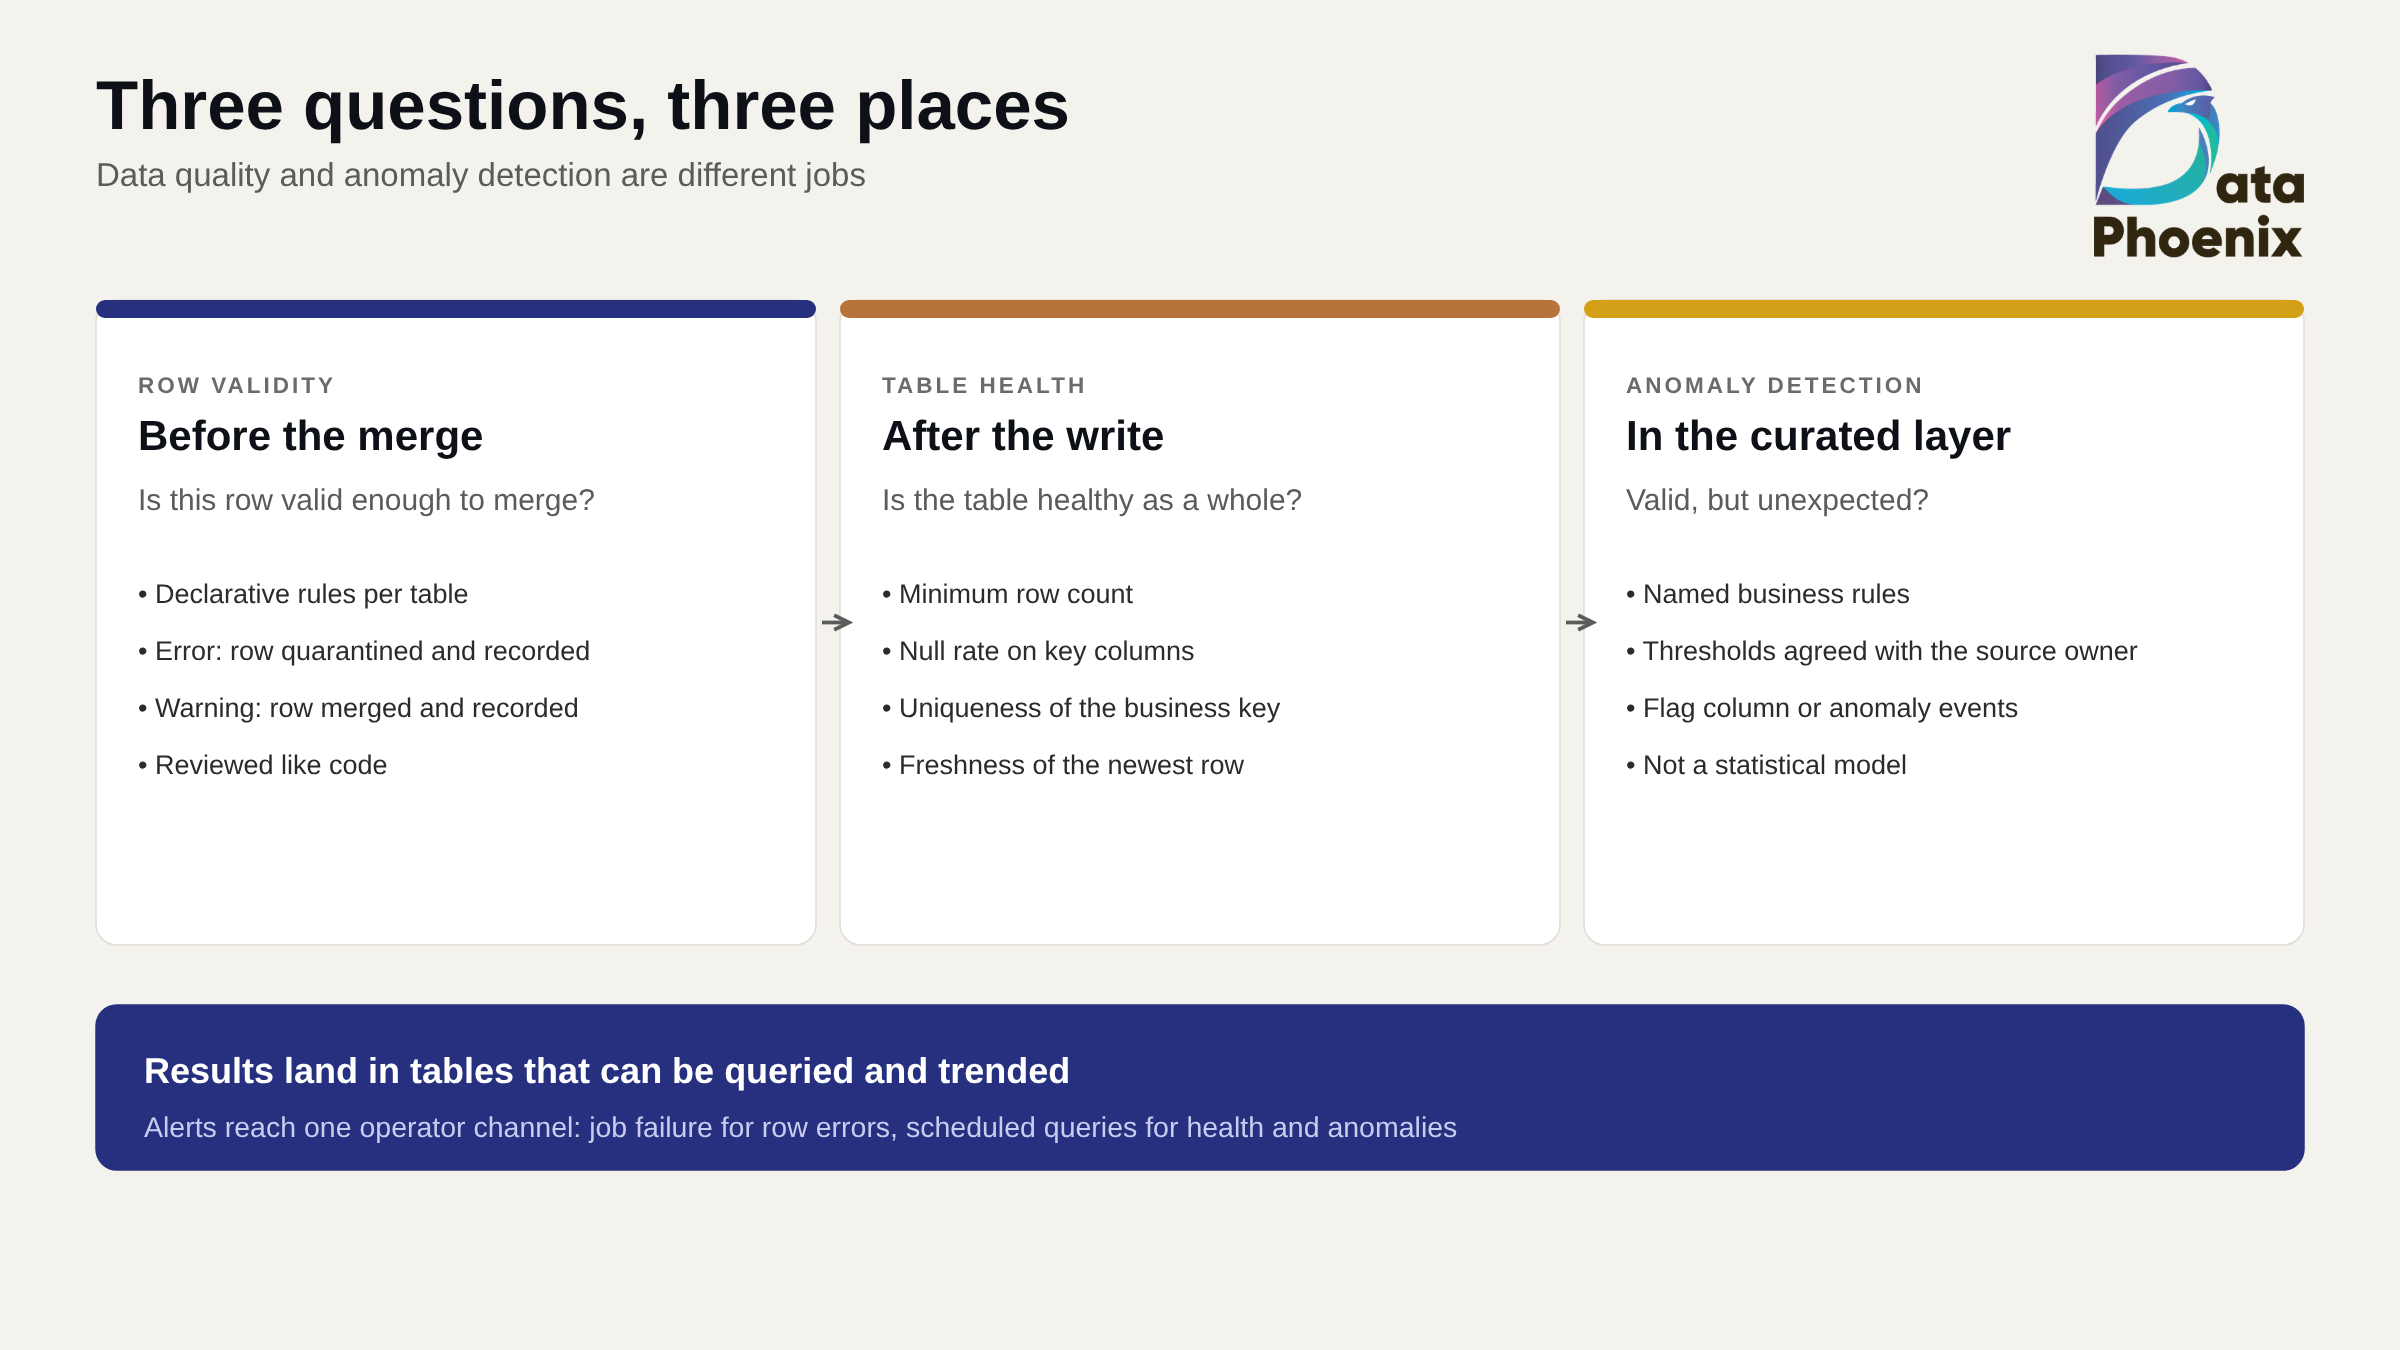
The first question is whether an individual row is valid enough to be merged into the refined layer. The checks run in the refined-layer job, before the merge, and are written as declarative rules, one file per table, kept in the repository and reviewed like any other change. Each rule carries a criticality. A row that fails an error rule is quarantined: excluded from the merge and recorded. A row that fails a warning rule is merged and recorded. A null merge key is an error. An out-of-range measurement is usually a warning. An invalid code value is one or the other, depending on how much the table depends on it.
The second question is whether the table is healthy as a whole once the write has finished. These checks run as a separate task that reads the written table, not the data in flight. Each check returns one row: a minimum row count, the null rate on key columns, uniqueness of the business key, freshness measured as the age of the newest row, and completeness of code lists. The results are appended to a results table, so they can be queried, trended and put on a dashboard.
The third question is whether the data shows a pattern that is valid but unexpected, which points to a problem at the source or in a process that no row check would catch. This happens in the curated layer, from refined data, and it is deliberately not a statistical model. Each anomaly is a named business rule with a threshold agreed with the source owner. An asset registry that says a server is retired while monitoring still reports it active is the classic example: both rows are valid, and the combination is not. The result is a flag column on the curated table, or a table of anomaly events.
A threshold lives where it is enforced: in the rule file, in the check module, in the alert definition or in the transform that sets the flag. Every change goes through review. Alongside the code, each source keeps a short human-readable record of what each threshold is, why it was set there and who agreed to it, and a threshold change updates both in the same review.
Every violation reaches one operator channel. When the error rate for a table passes its limit, the job fails, and the job’s own failure notification does the work, so row-level problems need no separate alerting system. Table-health results and anomaly flags are watched by scheduled queries that alert when a check has failed. Error alerts run frequently, and aggregate alerts run at a pace that matches how often the pipeline does.
It is tempting to build a layer that senses and repairs schema changes during ingestion. DataPhoenix recommends against it. The raw layer is a faithful copy of the source and the audit trail, so any in-flight adjustment, such as coercing a type, dropping a removed column or renaming a field, corrupts the record. If a source changes without notice, the raw layer should fail and alert.
Column additions are the only benign case, and storage-format schema evolution handles them at no cost. Removals, renames and type changes need a decision from the source owner that cannot safely be automated, and the mechanisms already in place cover them: data contracts that prevent unannounced change, pipeline failure with notification, and row checks that catch a required column quietly turning null. A dedicated sensing layer would duplicate all of that and add compute cost to every run.
Because the framework is configuration, a new source needs four additions: a rule file for each refined table, an aggregate check module, the threshold record and the job tasks that run the checks and the alerts. Threshold values are agreed with the source owner before the source is treated as operational. This is the quality step of delivering a new data source, and it belongs to the wider data governance design.